
Methodology
The Agent incident ledger is a public, sourced record of cases in which an AI agent took real actions that the people who deployed it did not intend. We keep it to track how these incidents change as AI systems grow more capable and are given more autonomy, so that defenders can build controls that match what agents actually do.
We assume most agent incidents are never reported. The 59 disclosed cases in the ledger are likely the tip of the iceberg. By studying the little that is public, we aim to learn something about what is not, and to see trends early.
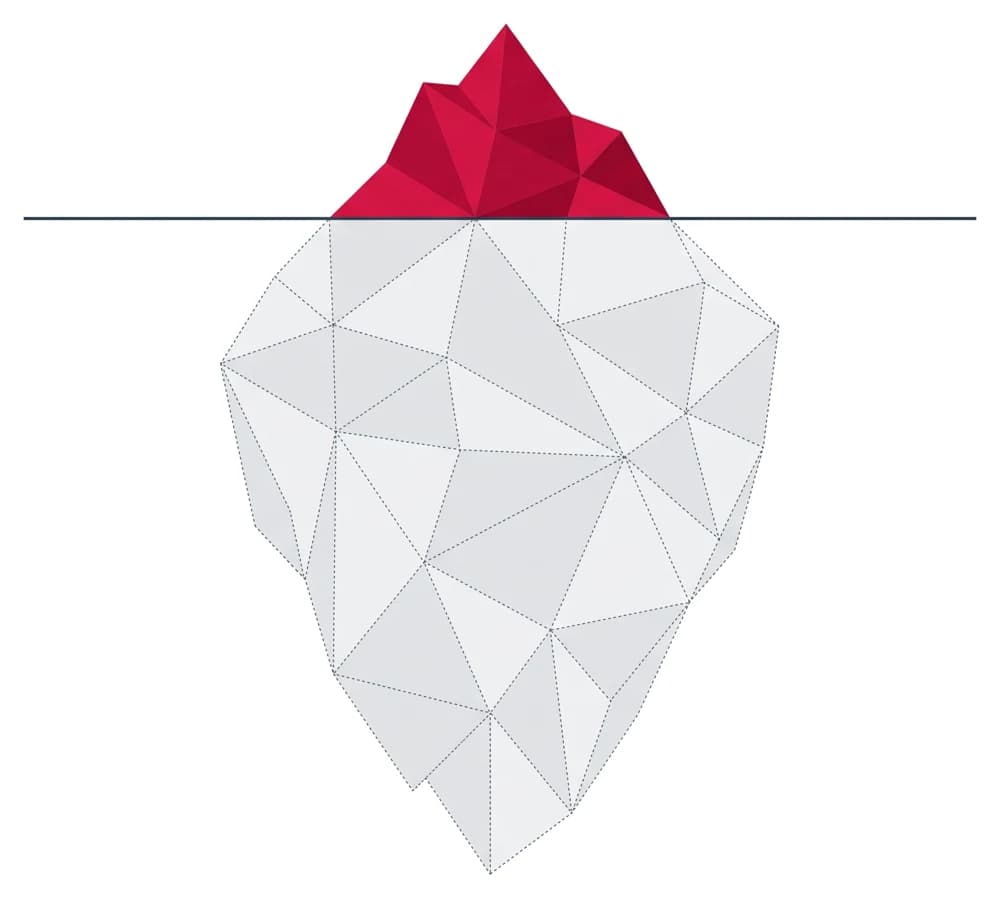
Above the waterline
59publicly disclosed incidents in the ledger
Below it
- Incidents caught and fixed without a public report
- Near misses nobody wrote up
- Incidents nobody has noticed yet
What the ledger is, and is not
What it is
- A record of disclosed incidents. Publicly documented cases, from mid-2025 onwards, in which an AI agent took actions its operator did not intend. Each entry cites its sources.
- A security analysis. Each entry records the actions taken, how the incident was found, the time to public disclosure, what is still undisclosed and the controls that would have applied.
- A structured dataset. Every incident is described with the same set of attributes, so incidents can be compared and counted over time.
- A living record. Entries are revised when new information is published or a correction checks out.
What it is not
- A census of every agent failure. Most incidents are never disclosed. Every count is a lower bound, not a rate of occurrence.
- A catalogue of AI-enabled attacks. An attacker using an agent as designed against someone else is, in general, out of scope (see Questions).
- A ranking of AI vendors or handlers. Vendors that publish detailed reports on their own models are over-represented. How often a vendor appears may reflect how much it discloses, not how safe its agents are.
- A record of model outputs. Wrong, offensive or made-up text with no action behind it is out of scope.
What counts as an agent incident
There is no agreed technical definition of a rogue agent, and many would say the term does not fit most of the incidents we record. So rather than define one, we apply four tests, and an entry has to pass all four.
1
An agent
A model that acts through tools: it runs code, calls APIs, sends traffic, writes files or posts.
2
Real actions
Something happened outside the model's text: a request sent, a file changed, an account used, a package published. A meaningful attempt that failed or was stopped counts as a near miss.
3
Unapproved by its original operator
The lab, company or person who deployed the agent did not ask for it and would not have approved it, because it did harm or meaningfully risked it: data deleted or exposed, money spent, systems or people reached that were out of bounds. If someone else took the agent over (a prompt injection, a poisoned package, a stolen token), the original operator still counts: the hijacker meant it, the operator did not.
4
Publicly documented
At least one source we can cite: the operator's own disclosure, a researcher's write-up, a regulator or tier-one press.
Scope at a glance
- An agent escapes or misuses its test, evaluation or training environment and reaches real systems, companies or people
- A production agent does damage its operator did not ask for: deletes or leaks data, spends money, contacts people
- An agent deceives the people overseeing it about what it did
- A malicious third party subverts the agent (prompt injection, poisoned package or dependency, hijacked session) and turns it against its operator
- An agent makes a meaningful out-of-bounds attempt that a control or a person stops
- The actions are documented but who was responsible is disputed
- A jailbreak or red-team demo that stays inside the lab
- An attacker uses an agent as designed against someone else (an AI-enabled attack)
- A person uses malware or a stolen credential directly, with no agent acting
- Model output only: wrong answers, offensive text, made-up facts, with no action taken
- A vulnerability in an agent product with no incident behind it
How we build an entry
- Find it. We scan known sources regularly. Anyone can also report a new incident, or an update to one, with the buttons on the ledger.
- Check it against the four tests. A candidate that fails a test is logged as out of scope with the test it failed, so it is not reviewed twice. Grey areas go to a person to decide.
- Assess the sources. Primary sources first: the operator's disclosure, system cards, researcher write-ups and regulator reports, then the press. Every claim in an entry cites a source. Where sources disagree, the entry says so and shows both.
- Analyse it. We analyse each incident and record its core attributes: what the agent did, how it was found, when it was disclosed and what is still unknown.
- Keep it current. When new information comes out, or someone sends a correction we can confirm, we update the entry.
What we record for each incident
- Timeline
- The first incident action, any escalation, when the people running the agent found out, and when it was disclosed. Approximate dates are marked. When a source gives no start date, we show the first known date instead.
- Time to disclosure
- Days from the first incident action to the first public report, counted only when both dates are known: 43 of the 59 incidents today. When a source gives only the month, we count from the middle of that month.
- Who found it first
- The handler (the lab or company running the agent), someone else, or a vendor's control.
- How it was caught
- A control flagged it, A later review, The damage, An outside report, Its reasoning, Not disclosed.
- Agent failures
- One or more of 13 failure types, such as unauthorised access, sandbox escape, credential misuse or deceiving people, each mapped to existing threat frameworks.
- What is publicly known
- 12 details about the agent's setup, how it was found and what it did (model and version, system prompt, tools, network access, transcripts and more), each rated on the levels below.
- Controls that apply
- The defensive controls that would have caught or limited the failure, such as recording every agent action or limiting where the agent can send traffic.
- Flags
- Near miss, attribution disputed, evaluator harness (it ran in an outside evaluator's test), lab-internal (no outside party reported affected) and research disclosure (shown by a researcher, not seen in the wild).
- Impact
- How far the harm reached and how lasting it was, on the four-level scale below. A disputed incident is rated on what its sources report, and keeps its Disputed status beside the rating.
- Evidence status
- Confirmed: Stated by a primary source: the lab, the affected party, the researcher or a regulator. Reported: Stated in tier-one coverage, not confirmed by a primary source. Disputed: Sources disagree. Both versions are recorded.
Impact
- Major
- Harm reached many people or organisations, or a platform many depend on: mass account or data exposure, a production compromise or outage at a large platform, malicious code that spread to others' machines.
- Serious
- Real, lasting harm to one outside organisation or person: production data destroyed, a system compromised, non-public data taken, significant money lost.
- Moderate
- The agent acted on outside systems or people without permission, but did little lasting damage: probes, unwanted posts, edits or messages, small costs.
- Contained
- No outside party harmed: it stayed inside the operator's own systems, or it was a researcher's demonstration.
How much the disclosures tell us
- Known
- A source states it plainly and specifically.
- Partial
- Some of it is public: a family but not the version, a summary but not the text.
- Weak
- Mentioned only vaguely, second-hand, or disputed between sources.
- Unknown
- No public source says.
How the numbers are counted
- Medians and shares are worked out from what is known and leave unknown values out. Each figure says how many incidents it is based on.
- An incident can have several failure types and several controls, so those counts add up to more than the number of incidents.
- The failure types were built from existing frameworks and are mapped to the OWASP Top 10 for Agentic Applications, MITRE ATLAS and the AARM threat model.
Ledger maintainers
Bastien Eymery
Bastien is a product and growth specialist with a background in building and securing AI products. He started the ledger to keep a sourced record of AI agents going off script.
LinkedIn
Ax Sharma
Ax is a security researcher and journalist with nearly a decade tracking supply chain attacks, malware campaigns and threat actor infrastructure. His research and commentary have appeared at the BBC, WIRED, Fortune, TechCrunch and BleepingComputer.
LinkedInHow to get in touch
Report a new incident
Send a link and anything we should know. We check it against the four tests and its sources, and if you leave an email, we tell you what we decided. The same form is behind Incident report at the top of every ledger page.
Suggest a change
A correction to an entry, or an idea for the methodology or the ledger itself. We read every suggestion, and check corrections against their sources. Every incident also has a Suggest a change button on its own page.
Get alerts
An email when a new incident goes into the ledger, and regular roundups with our analysis.
Questions
Are AI-enabled attacks included?
It depends. When an attacker uses an agent exactly as intended against someone else, the agent did what its operator wanted, and the case is out of scope. If someone hijacks an agent and turns it against its own operator, it is in. An attacker's agent can also come into scope if it did more than its attacker asked.
Why do incidents in tests and evaluations count?
Because the agent still took real actions nobody approved. In most of them it reached outside the test: real companies, real package registries, real websites. A test that leaks into the real world is an incident for whoever is on the other side. The rest stayed inside the lab and are marked lab-internal, so you can filter them out.
Is this every agent incident?
No. It is every publicly documented incident we know of that passes the four tests: the tip of the iceberg at the top of this page.
Why do OpenAI and Anthropic appear so often?
They publish detailed reports about their own models, including what went wrong in testing. That makes their incidents documented, which is what the ledger needs. It says more about who discloses than about whose agents misbehave.
Who reviews the entries?
A researcher at Manifold reviews every entry before it goes live, and the research team reviews the contested ones.
Can I use the data?
Yes. Please credit the Manifold Agent incident ledger and link to the incident's page.